Getting a new model to run is one step. The engineering that follows is integrating it into the serving stack, establishing a performance baseline you can trust, and tracing bottlenecks across the model, runtime, software, and hardware. In this case the bottleneck wasn’t the GPU.
I set out to do something that sounds simple: take a published benchmark for DeepSeek V4 Pro on B200, reproduce it, and see if we could beat it. It took about two weeks. This post is the record of what actually went wrong, because the two weeks say more than the final number does.
The benchmark came from InferenceX. The obvious first move was to pull their image, run their config, and confirm the same numbers. That didn’t work, for two separate reasons.
First, the exact vLLM image InferenceX used wasn’t pullable from any registry I had access to — whatever they built it from wasn’t published anywhere I could reach.
Second, and more important for what I actually cared about: InferenceX ran on pure vLLM, without Dynamo. For running this at scale on Kubernetes in production, pure vLLM isn’t where things are heading — Dynamo is. So even a perfect pure-vLLM reproduction wouldn’t answer my real question. I chose to run the same model on Dynamo, and that’s where the work started.
Reference I was trying to reproduce (InferenceX, B200, pure vLLM):
- Image: vllm/vllm-openai:nightly-3f0a91bb96f8d72e0498b95c166e817deae14d62, Date 2026-06-05
- Throughput: 4074 output tok/s/gpu (8151 total, in 4077 / out 4074), Interactivity 8.334 tok/s/user
- 8×B200, single-node aggregate, TP=8, EP=8, DP-attention, concurrency 4096, FP4
Wall #1: the model didn’t exist in the engine yet
I began from the obvious baseline — the current published Dynamo image, v1.1.1 — running the DeepSeek-V4-Pro-NVFP4 checkpoint with the unsupported flags stripped out. It failed immediately at model load: that Dynamo release bundles a vLLM old enough that the deepseek_v4 architecture isn’t registered at all. Not a tuning problem — the code for this model simply wasn’t in that engine. In hindsight the wrong starting image, but that’s exactly the kind of thing you only learn by hitting it.
I moved to a release actually built for this model, v1.2.0-deepseek-v4-dev.3, restored all the relevant InferenceX flags, and tried again. New failure, and a cleaner one:
KeyError: ‘layers.0.ffn.experts.w13_input_scale’
After comparing my configuration against NVIDIA’s official B200 vLLM recipe, I fixed all the remaining flag and configuration mismatches. The KeyError still didn’t go away. That’s when I realized the problem wasn’t the flags at all.
Wall #2: the checkpoint was the actual problem
The `w13_input_scale KeyError` persisted regardless of –moe-backend (including unset) and at TP=8 — which ruled out the flags entirely. The cause was the checkpoint itself.
DeepSeek-V4-Pro-NVFP4 is a ModelOpt NVFP4 export built for TensorRT-LLM: its routed experts carry static per-expert input scales (w13_input_scale/w2_input_scale). vLLM’s deepseek_v4 loader expects the original deepseek-ai/DeepSeek-V4-Pro checkpoint, whose experts use dynamic activation scaling and therefore have no such tensors — so the loader has no slot for them and dies at weight load. Switching to the original checkpoint removed the KeyError.
Now the model ran and produced correct output — but at roughly half the throughput I expected. Correct, but slow.
Wall #3: the image was the bottleneck
I wanted to try building a custom image on the exact nightly vLLM base InferenceX used, with ai-dynamo installed on top — but that nightly base wasn’t pullable either.
So I looked at an earlier InferenceX run (June 1) on vLLM 0.22.0, whose tok/s/gpu was close enough to be a fair target:
- Image vllm/vllm-openai:v0.22.0: 3900 output tok/s/gpu (7803 total), Interactivity 7.939, same 8×B200 / TP=8 / EP=8 / conc 4096 / FP4 setup.
To isolate the problem, I first ran pure vLLM 0.22.0, no Dynamo — and hit the expected numbers. That confirmed it: the model, the checkpoint, and the flags were all fine. The bottleneck was the Dynamo image.
I wanted a Dynamo image on vLLM 0.22.0.
Per the support matrix (Support Matrix | NVIDIA Dynamo Documentation) I tried v1.3.0-dev.1, and got a new failure: a nvidia-cutlass-dsl import error — even a bare import cutlass failed with cannot import name ‘increment_coord’ from ‘cutlass.cute.core’. I filed it upstream ([BUG]: ai-dynamo/vllm-runtime:1.3.0-dev.1-cuda13 ships a self-inconsistent nvidia_cutlass_dsl (missing `increment_coord`) — `import cutlass` fails · Issue #11775 · ai-dynamo/dynamo), and the maintainers confirmed it.
To be clear about the sequence: I selected this image the only way a user reasonably can — from Dynamo’s support matrix, which lists v1.3.0-dev.1 as the vLLM 0.22.0 build. The failure is real, reproducible, and worth reporting, and filing it against Dynamo was the right call: that’s the image the matrix points you to, and it’s broken the moment you pull it.
The refinement that came out of the thread is about attribution, not validity. The defect isn’t something Dynamo’s build introduces — it’s inherited from the vLLM base image Dynamo starts from, vllm/vllm-openai:v0.22.0-ubuntu2404, which already fails the same import cutlass before Dynamo adds a single layer. The same bug effectively lives in two places, and the durable fix belongs further upstream — in the cutlass-dsl packaging, and in the vLLM base that pins it. Here’s the part that actually cost me time: had the support matrix listed the concrete base image tag instead of just “vLLM 0.22.0,” this would have been diagnosable as a vLLM-base problem from the start — the report could have gone straight upstream, and I’d never have suspected Dynamo’s build layer at all. That one missing tag is the same gap I hit when choosing my comparison base, below.
Root cause, in one line: on CUDA 13 the nvidia-cutlass-dsl package installs two sub-wheels that overwrite each other’s files, leaving a mismatched cutlass that can’t import. (The full wheel-collision breakdown is in the issue thread if you want it.)
Rather than wait, I patched around it with a one-liner that forces the correct wheel to win last:

It booted clean — but the throughput was still low.
Side-lesson: ‘pip show vllm’won’t tell you which image you’re on.
My first instinct was to compare against vllm/vllm-openai:v0.22.0 — the wrong control. `pip show vllm` reports 0.22.0 in both the v0.22.0 and v0.22.0-ubuntu2404 images, because pip knows the library, not the container it sits in. But the -ubuntu2404 tag is exactly what decides whether the colliding CUDA-13 wheels get pulled. The fix is to ask the image itself instead of guessing the tag:
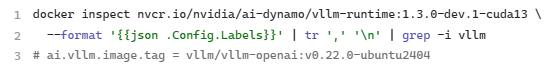
The broader lesson: reproducibility depends on the full software environment, not just the inference-engine version. Two images can report the same vLLM version while differing in their base image, CUDA dependencies, or packaged libraries enough to determine whether the workload runs at all. For benchmark reproduction, the image and its dependency stack are part of the configuration.
To put this detour in context: all I wanted was a Dynamo image running the vLLM 0.22.0 package, so I could reproduce the InferenceX 0.22.0 result on Dynamo. The support matrix pointed me to exactly that — v1.3.0-dev.1 does ship vLLM 0.22.0 — but the image tag behind it (v0.22.0-ubuntu2404) pulls the colliding CUDA-13 cutlass wheels, so the package was right while the image was broken. That mismatch is the whole reason a simple “reproduce a 0.22.0 number” task turned into filing a bug and hand-patching a runtime before I could even start measuring.
Wall #4: Dynamo vs pure vLLM
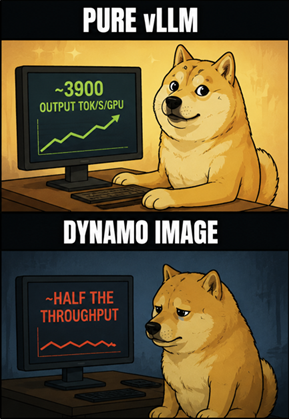
With a working Dynamo image whose vLLM/CUDA/library versions I’d verified were identical to the pure-vLLM image, the gap had to be Dynamo-side.
I first suspected the single frontend and added more frontend replicas (with DP=8, there are 8 API-server engines behind it) — no change. To locate the bottleneck I read the vLLM logs directly: ~256 running requests with nothing queued. The GPUs weren’t starved for work at the engine — so the loss was on the host side, not in compute — my first guess was routing/queuing between the frontend and the engines (it wasn’t, but that’s where I looked next).
I swept concurrency, thinking we weren’t feeding it hard enough — but above ~1024 the throughput flattened to the same ceiling every time. Classic serialization limit, not a utilization limit.
At this point I was convinced the bottleneck wasn’t on the GPU. The logs showed a modest number of running requests with nothing queued – the engine wasn’t starved for work. Something on the host side was preventing the GPU from staying busy.
While reading through the vLLM documentation, I came across a subtle difference between native vLLM and Dynamo when running with DP > 1:
- –api-server-count serve – vLLM
- –stream-interval serve – vLLM
I tried increasing –stream-interval from its default value of 1 to 10, and throughput immediately improved. Only afterward did I dig into why a single configuration change had such a large effect.
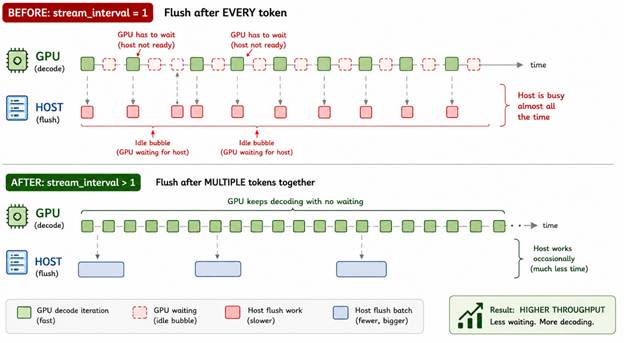
Here’s what actually happens during every decode step.
The GPU performs one forward pass and generates one new token for every active sequence. After that, the CPU must detokenize the generated tokens, serialize them into SSE/JSON responses, and send them over the network.
GPU decode scales very efficiently with batch size. As the number of active sequences grows, the GPU can process larger batches with only a modest increase in compute time because the work is executed by highly optimized, batched kernels.
The host output path does not scale that way. Its work is proportional to the number of generated tokens: detokenization, serialization, and socket writes are Python code executed by a single output process.
Eventually those two curves cross.
Below the crossover point, GPU compute takes longer than host output processing, so decoding proceeds continuously.
Above it, the GPU finishes each forward pass and waits for the host to finish streaming the previous step’s tokens before starting the next one. Those idle periods become throughput-killing bubbles.
The measurements (before my fix) matched this exactly:
- Concurrency 1024: ITL ≈ 48 ms. Host processing fit inside the decode step, so decoding proceeded without stalling, producing 18,951 output tokens/sec.
- Concurrency 4096: ITL 253 ms, throughput 10,946 output tok/s. The engine logs showed a modest number of running requests – far fewer than 4,096. Little’s Law confirms it: N=10,946×0.253≈2,770 sequences were actively in flight on average – meaning the engine was not saturated at the requested concurrency.
The fix was surprisingly simple.
Setting –stream-interval 10 changes only the output path. Instead of emitting a streaming update after every decode step, the engine continues decoding normally while buffering generated output. Roughly every tenth step, the accumulated output is emitted together.
That reduces host overhead because streaming output is emitted roughly ten times less frequently. Instead of paying the fixed Python, response-construction, serialization, queueing, and network overhead for every generated token, that work is amortized across multiple tokens in each output event.
Incremental detokenization can still happen as tokens are generated; the key difference is that the downstream response and streaming path is invoked much less frequently.
Nothing changes on the GPU. The engine still performs one decode step after another. The difference is that the CPU no longer has to process and emit a streaming response after every single decode step.
With the host no longer pacing execution, the GPU could sustain much larger batches before hitting the crossover point.
The improvement was immediate:
- Concurrency 2000: throughput increased to 28,108 output tokens/sec.
- Concurrency 3500: throughput climbed further to 30,617 output tokens/sec.
- Concurrency 4096: throughput remained stable at roughly 31,000 output tokens/sec, instead of collapsing as it had before.
The key insight was that nothing on the GPU had changed. The entire bottleneck was the host output path.
Same GPU, different plumbing on the host side
–stream-interval significantly delayed the host-side bottleneck, but it didn’t remove it. Dynamo still has a single output process. Native vLLM solves the same problem differently: instead of amortizing the work, it parallelizes it using –api-server-count, spawning multiple independent output processes. Each process has its own Python interpreter and GIL, allowing host-side output work to scale across CPU cores.
| Native vLLM | Dynamo | |
| Output processes | N | 1 |
| Independent GILs | N | 1 |
| Host output capacity | N× | 1× |
Native vLLM and Dynamo execute the same GPU kernels. The difference is entirely on the host side: native scales output processing by adding more output processes, while Dynamo currently relies on a single output loop. –stream-interval significantly delayed that bottleneck, but true host-side parallelism is what would likely close the remaining gap.
The broader lesson is that the inference engine is only one part of the system. The orchestration and serving layer can change the process topology, parallelism, and host-side execution enough that the same engine and GPU configuration produce very different end-to-end performance.
At concurrency 4096, using –stream-interval 10, I reached roughly 31,000 output tokens/sec, corresponding to about 3,889 output tokens/sec/GPU. Compared to the original run, the GPU was finally able to sustain much larger decode batches without repeatedly stalling on host-side output processing.
Running a longer benchmark afterward, with a more stable measurement window and less influence from warm-up and tail effects, produced an even higher sustained throughput of 34,041 output tokens/sec, or 4,255 output tokens/sec/GPU.
At comparable interactivity, roughly 8.3 tok/s/user, that exceeds every published InferenceX result I compared against:
- the vLLM 0.22.0 benchmark I used as my reproducible target, 3900 output tok/s/gpu
- the later nightly vLLM benchmark (whose image is no longer publicly available), 4074 output tok/s/gpu
- and the more recent vLLM 0.25.0 benchmark published afterward, 3604 output tok/s/gpu
Against the closest comparison, the nightly run at 4074 output tok/s/gpu and 8.334 tok/s/user, this comes out about 4% ahead at effectively the same per-user interactivity. On the same box, the fix took throughput from 10,946 output tok/s to 34,041. That gap was never a GPU or model difference.
The next experiment is to revisit concurrency 4096 with different –stream-interval values to identify where the amortized, single-process output path reaches its practical limit. Larger values of the stream-interval further reduce host overhead, but they also delay when generated tokens are flushed to the client, increasing TTFT (time to first token). Finding the right balance between throughput and responsiveness is therefore the next optimization to explore.

The point of writing this down
None of this was in the documentation. Reproducing a published benchmark turned out to require finding a broken checkpoint, an incompatible image, a bug in a public repository, and finally uncovering a host-side bottleneck that had nothing to do with the model or the GPU. The whole process took about two weeks.
The interesting part wasn’t beating the published benchmark—it was discovering that the limiting factor wasn’t the GPU, the model, or even the inference engine itself. It was a single host-side output loop hiding behind what initially looked like a GPU performance problem.
If a write-up like this had existed before I started, my guess is the entire investigation would have taken a few hours instead of weeks.
That’s exactly the value we want to provide with NR-NEXUS™. Users shouldn’t have to spend weeks debugging inference stacks, comparing images, patching runtimes, or chasing hidden bottlenecks. We want to do that work for them, so they can focus on their applications while benefiting from the performance improvements.